What is UniScribe?
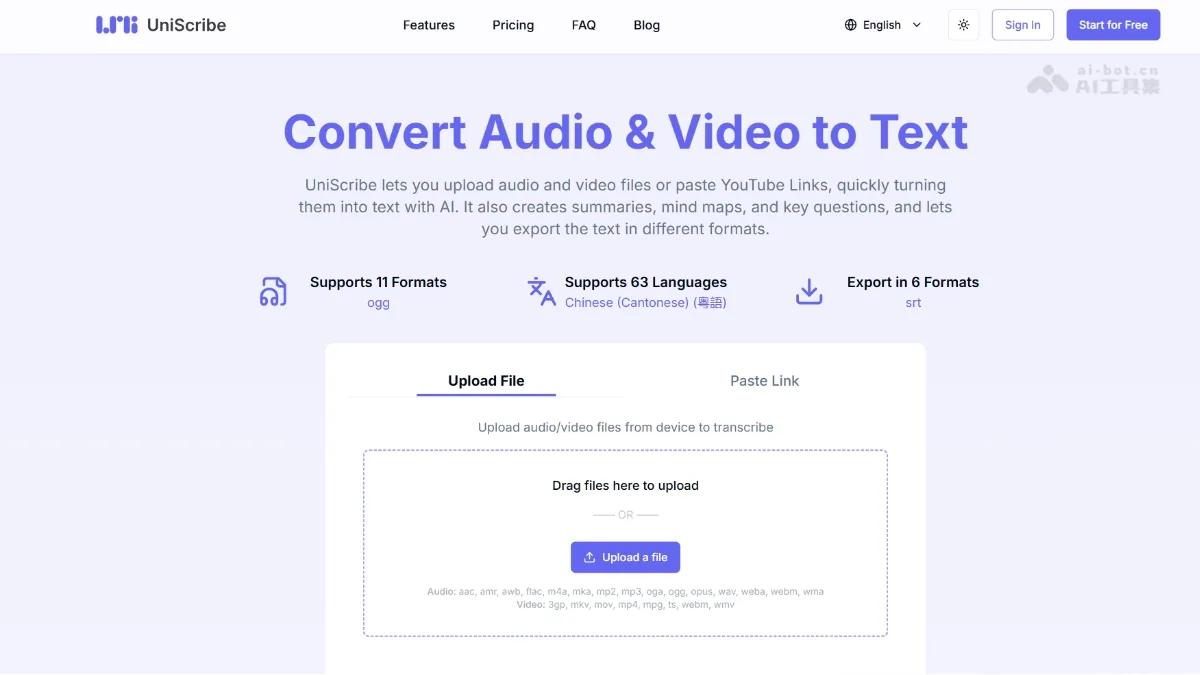
UniScribe integrates transcription, content organization, and export into a single workflow. Users can upload audio or video files or paste supported video links to obtain searchable and editable transcriptions, which can then be further used to generate summaries, key questions, or mind maps.
The official website supports multiple languages and common media formats, and allows exporting in TXT, DOCX, PDF, SRT, VTT, and CSV. These different formats are suitable for document organization, subtitle creation, or data processing; subtitle files should not be confused with complete audio‑video productions.
Recognition quality is affected by recording quality, background noise, and language selection; editing the output before exporting makes it more suitable for formal use. Free and paid plans differ in terms of minutes, file length, batch uploads, and retention periods, and the actual processing speed cannot be estimated solely based on the examples provided on the official website.
Key features
Audio and Video to Text
Supported online video link transcription
Speaker and timestamp
Summary, Key Issues, and Mind Map
Document, Text, and Subtitle Export
Use cases and audience
Users who need to organize recordings, courses, and interviews
- Meeting and Interview Summaries
- Course and podcast notes
- Subtitles and searchable transcriptions
Audio, video files, or supported online video links
Transcription, summaries, mind maps, and subtitles/document files
How to use
- 01
Upload audio or video files, or enter a supported link.
- 02
Confirm the language and initiate transcription.
- 03
After verifying the speaker, timestamp, and text, export or share.
Benefits and limitations
Benefits
- Multilingual high accuracy
- Support multiple audio and video formats
- Free transfer minutes
- Generate summary and mind maps
- Provide multiple export options
Limitations
- Free scheme limits on the transfer of minutes and daily documents
- Certain functions are limited to payment plans
- Accuracy depends on audio quality
Pricing and availability
Free entry available
120 minutes of record time per month. Limited to five documents per day. Standard transfer model (general speed). Supporting the transcription of 98 languages. TXT, SRT, VTT export format. Text summary. Thinking guide generation. Question and answer extract. YouTube. Media documents are kept for 30 days. E-mail support provided。
Twelve hundred minutes per month. There is no daily limit for the reproduction of documents. Advanced transfer model (super fast). Supporting the transcription of 98 languages. Word, CSV, PDF, TXT, SRT, VTT export format. Text summary. Thinking guide generation. Question and answer extract. YouTube. Media documents are available for an unreserved period. Priority e-mail support。
6,000 minutes per month. There is no daily limit for the reproduction of documents. Advanced transfer model (super fast). Supporting the transcription of 98 languages. Word, CSV, PDF, TXT, SRT, VTT export format. Text summary. Thinking guide generation. Question and answer extract. YouTube. Media documents are available for an unreserved period. Priority e-mail support。
2026-10-24 Verification of the official Free plan: 120 minutes per month, up to 3 files per day, with a maximum of 30 minutes per file, processed one at a time; media files are retained for 30 days. The paid plans offer extended file lengths and batch processing capabilities separately; free minutes are not interpreted as unlimited transcription. Source: https://www.uniscribe.co/
- Pricing source
- https://www.uniscribe.co/
- Pricing last updated
- 2026-10-24
Prices and limits may change. Check the official website for current terms.
Official website & sources
Sources
Updated on 2026-10-24