
Configure, Certify, and Operate Kubernetes GPU Clusters with NVIDIA DSX OS
One underperforming GPU can slow an entire distributed training job. The node may pass basic health checks and show normal utilization, leaving operators to...
Follow the latest facts and developments on one topic.
One underperforming GPU can slow an entire distributed training job. The node may pass basic health checks and show normal utilization, leaving operators to...
arXiv:2611.06207v1 Announce Type: new Abstract: Achieving performance portability is challenging for irregular scientific applications built as repeated multi-kernel GPU pipelines, because throughput depends on out-of-kernel decisions as much as on kernel efficiency. Using molecular docking as a representative case study, we propose an out-of-kernel tuning methodology that treats batching policy, worker concurrency, and per-worker memory allocation as explicit optimization parameters, replacing backend-dependent occupancy-driven choices with a more portable execution strategy based on explicit resource bounds. We implement this methodology in the muDock mini-app under a manager/worker execution model where multiple host workers share a GPU through independent streams. We then evaluate the methodology on NVIDIA, AMD, and Intel GPUs across CUDA, HIP, and SYCL implementations. Across all evaluated platform/backend pairs, the memory-bounded formulation exceeds the peak throughput of the occupancy-guided baseline. The fully tuned methodology improves the end-to-end throughput on all tested configurations, achieving an average speedup of 1.53x over the baseline.
Chris Alexiuk has a simple rule about open source AI: If you believe in it, be loud about it. “We should be shouting about this technology from the rooftops,” said Alexiuk, a Toronto-based senior product research engineer in deep learning at NVIDIA who specializes in making open large language models (LLMs) practical for working developers. […]
As GPU clusters scale, operations span compute, network, hardware, and scheduling. Site reliability engineers (SREs) often have to examine multiple dashboards...
As artificial intelligence and accelerated computing continue to push the boundaries of what's possible, the latest NVIDIA CUDA release arrives to unlock...
Hello everyone, I'm BIOcanse.Windows Task Manager has inaccurate readings and limited monitoring items. Various hardware adjustments are also very separated—CPU, GPU, and fans all require their own individual software. Their interfaces and interactions are primitive, and they often overwrite each other's configurations. Moreover, driver management of the CPU and GPU is too clumsy, and the memory usage issue on Windows is also very serious. So I made Resource Manager to view and manage all these resources in one place, making monitoring and scheduling work seamlessly together.Monitoring:This software integrates almost every possible monitoring item, letting you look at your computer from a God's-eye view!Scheduling:One of the core features. It uses algorithms I wrote to optimize memory usage and reasonably schedule processes across multiple CPU cores. It also supports GPU scheduling, which means it can switch the GPU a program uses while it is running. For example, after launching a game, if GPU usage is high or VRAM is about to overflow, it will move the remaining software to another GPU (for most personal computers, this is usually the integrated GPU).Reporting:Many times, computer performance problems are actually just caused by a single program or driver—the benefits of 100 programs optimizing themselves cannot make up for a memory leak in just one program. The reporting page reports abnormal resource usage (CPU, GPU, memory, VRAM, disk read/write, network traffic, and causing system interruptions).Hardware Adjustment:All the parameters you can think of for hardware like the CPU and GPU can be adjusted here. However, my own setup is an AMD CPU + NVIDIA GPU, so other setups still need to be verified. I do have several computers with Intel CPUs to verify Intel CPU support, but I really do not have a single AMD GPU. Although most of it uses mature open-source dependencies, there may still be risks, so please use it with caution. Comments URL: https://news.ycombinator.com/item?id=50380521 Points: 1 # Comments: 0
arXiv:2611.04222v1 Announce Type: new Abstract: Under expert parallelism, mixture-of-experts (MoE) layers pay all-to-all token dispatch, grouped GEMMs, and a combine step in every layer. In decode each rank holds only 1-256 tokens: dispatch latency and weight traffic dominate while tensor-core utilization is inherently low. In fused operators such as DeepGEMM's Mega MoE, dispatch and computation overlap only by sharing every SM: dispatch warps compete with TMA/MMA and epilogue warps for registers, shared memory, and issue slots; every phase shares one CTA resource budget, synchronization spans the whole SM array, and every replay ends with a workspace-clean pass and a cross-rank barrier. We present GC-MoE, an open-source FP8/FP4 MoE inference operator for NVIDIA Hopper and Blackwell GPUs that uses CUDA Green Contexts to split the device into a small communication partition and a large compute partition. Each role gets its own kernel, resource budget, and synchronization domain, so dispatch and GEMM tune independently. A three-node CUDA Graph (four on Hopper with fused shared experts) launches the dispatch and grouped-GEMM kernels as concurrent roots; a token-ring handshake starts computation on the first filled ring blocks, and double-buffered receive counters remove the trailing cross-rank barrier between replays. The compute partition runs operand-swapped tcgen05 block-scaled MMA on Blackwell and register-A WGMMA with in-register FP4 decoding on Hopper, with fused SwiGLU, requantization, and optional shared experts. On 8 H20 GPUs GC-MoE accelerates DeepSeek-V4.1-Flash decode by 1.188x on average on both the routed and shared-expert suites (peaks 1.296x and 1.353x); on 8 B300 GPUs it accelerates GLM-5.2 and DeepSeek-V4.1-Flash by 1.106x (1.123x with fused shared experts, peak 1.209x), beating Mega MoE at all 54 measured points at matched accuracy. GC-MoE reserves only 20 of 148 SMs on B300 for dispatch.
NVIDIA H100 GPUs are here, with better performance and lower cost.
This repo provides an alternative to the ontology compiling capabilities of NVIDA Auto-Ontology.The main difference is that it builds the ontology from most of your existing data assets (transformation code, dashboards, docs), instead of building it from your warehouse and semantic layer only.It consists in skills and python scripts that ingest the metadata and docs your team already has, and compile them into YAML and Markdown files structured in a file tree that an agent can use as context to query your data.When your existing asset contradict, or reveal a gap in the business context around your data, it writes down questions for you and your team instead of guessing a plausible meaning.It runs locally in any coding agent. Comments URL: https://news.ycombinator.com/item?id=50363667 Points: 1 # Comments: 0
arXiv:2611.01371v1 Announce Type: new Abstract: Token-based subscriptions are emerging as a commercial model for large language model inference, but extending them into interoperable utility services requires comparable consumption accounting. Raw token counts do not consistently measure inference resource use because demand varies with model architecture, context length, tokenisation, and concurrent serving conditions. This paper presents Token-as-a-Utility, a model-agnostic architecture integrating inference metering, service-level-aware provisioning, and inter-operator settlement. We prove that, under batched serving, no per-request meter can be additive, independent of co-resident traffic, and exactly cost-reflective at once. This motivates separating provisioned capacity, metered consumption, and contracted quality into distinct service products. Consumption is expressed in Reference Inference Units (RIUs) derived from prefill and decode demand, while occupancy-indexed operator ratings recover shared serving costs without altering the common unit. Versioned inference records support auditing and re-rating across operators; software-enforced capacity leases and quality-constrained routing enable provisioning on shared accelerators. The resource model is measured on three NVIDIA RTX 5000 Ada GPUs, and multi-tenant behaviour is evaluated with a trace-driven model calibrated to them. For the reference model, occupancy-indexed rating limits statement energy error to 9% under measured traffic, compared with up to 70.5% under fixed-occupancy rating. In calibrated multi-tenant experiments, tenant mispricing decreases from 7.36 times under flat token counting to 2.39 times with RIUs and 1.06 times after occupancy-based reconciliation. These findings demonstrate how portable inference accounting can be combined with load-dependent cost recovery and contract-based provisioning to support heterogeneous inference services across operators.
In distributed AI workloads, a single error can produce a cascade of symptoms. A GPU or fabric event may surface as NCCL errors on other ranks, scheduler state...
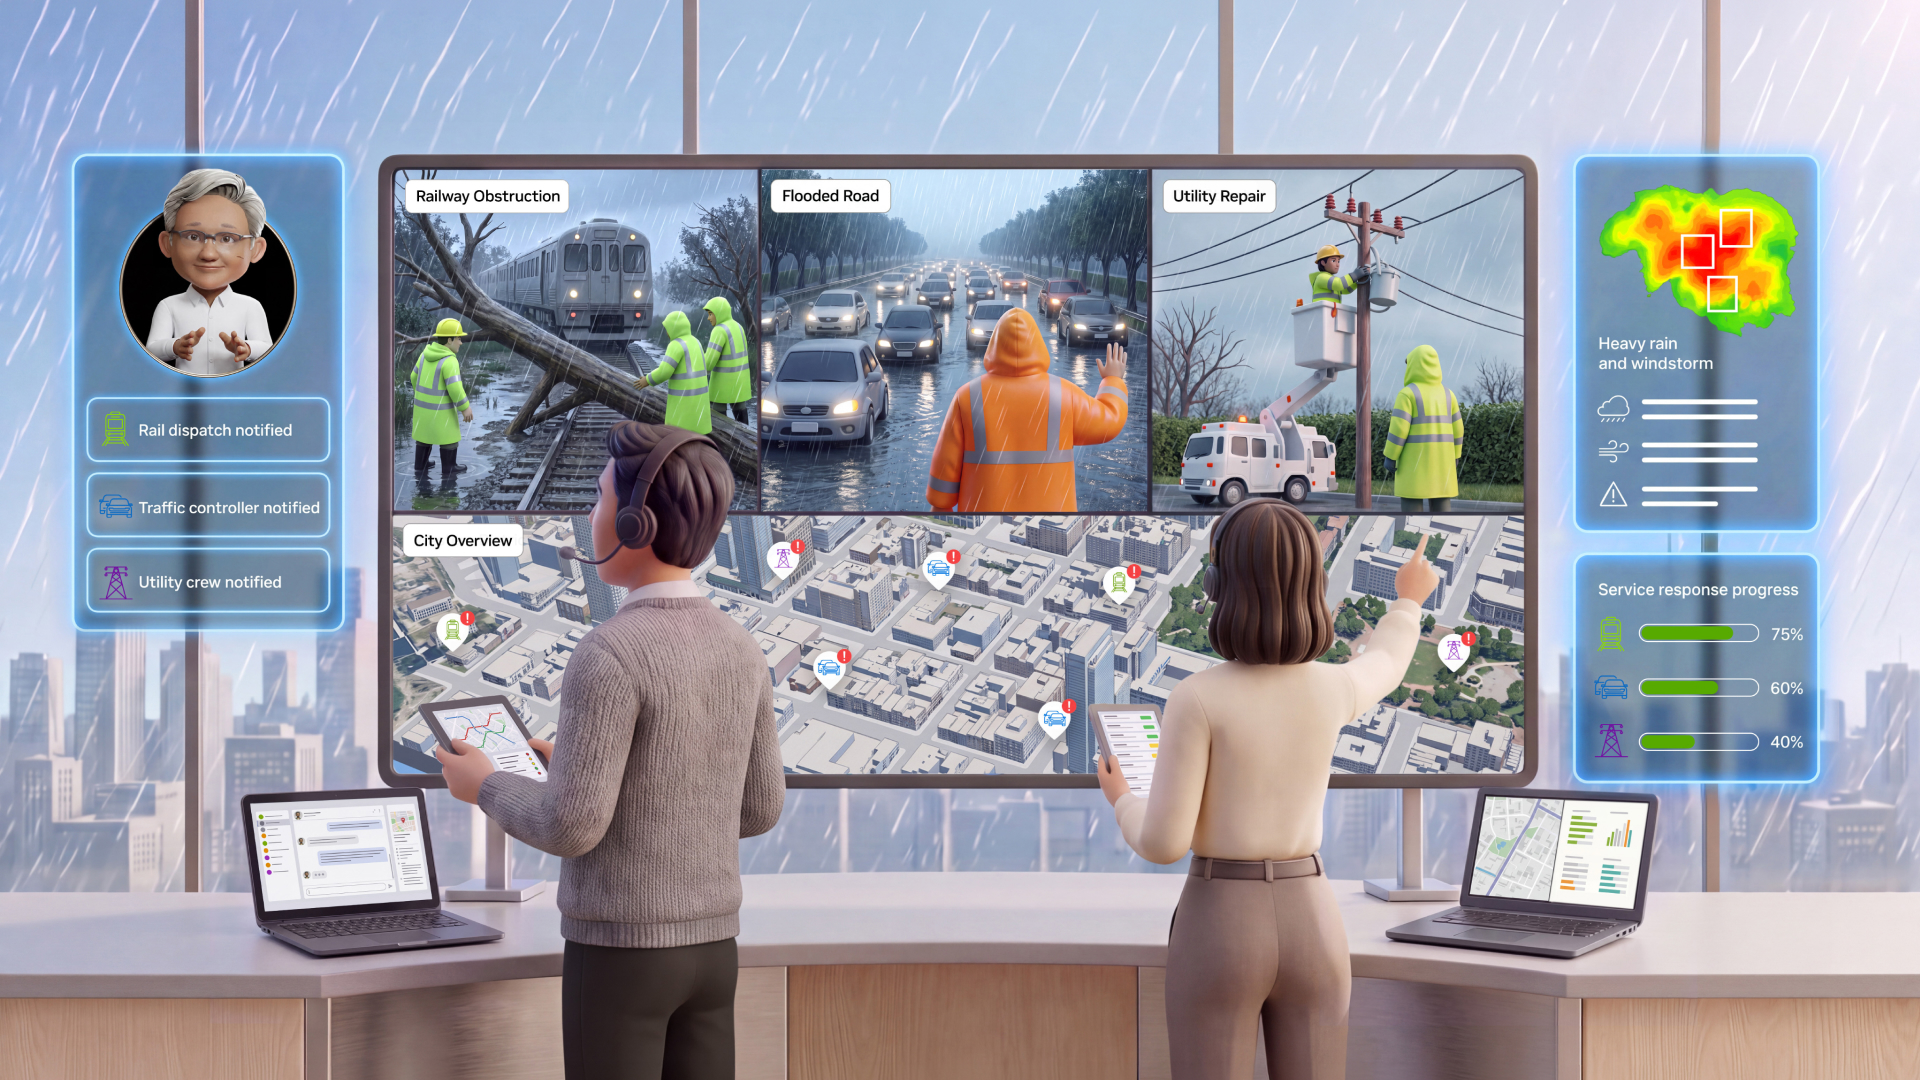
Cities generate enormous amounts of data from cameras, sensors and operational systems, but turning it into useful action — for planning, maintenance and public services — remains a challenge. Physical and agentic AI offer new ways to close that gap, from digital twins for infrastructure planning to vision and service agents, while keeping local governments […]
Building an autonomous agent requires a model, a harness, and domain-specific tools. To deploy an agent more securely, developers need a runtime that enforces...
NVIDIA has officially open-sourced its new large-scale speech transcription model, Nemotron 3.5 Transcribe. Designed for professional voice processing, this model leads the industry in key metrics such as multilingual transcription accuracy, long-audio handling, and multi-speaker separation. It employs a Mixture of Experts (MoE) architecture with approximately 34 billion total parameters, activating only a subset of these parameters during each forward pass to enhance efficiency. Overall, it provides a new open-source option for professional speech transcription.

A top executive of a Singapore AI cloud company that was accused of illegally selling Nvidia chips to China could also have been a Chinese spy, sources have told the New York Times.

Nvidia Corp. today released a leaderboard-winning open artificial intelligence model for multilingual audio transcription and translation, along with an open data pipeline for fine-tuning Nemotron 3.5 Transcribe. Traditional transcription AI models follow a workflow that detects speech, transcribes it, identifies and labels different speakers, then answers questions about the transcription. Transcribe does all of this […] The post Nvidia releases all-in-one adaptable Nemotron 3.5 audio transcription and translation model appeared first on SiliconANGLE.
NVIDIA RTX Spark powers thin and light laptops built for everything that developers, creators and gamers do. RTX Spark laptops are now available from ASUS, Dell, HP, Lenovo, Microsoft and MSI. These powerful systems combine an NVIDIA Blackwell RTX GPU and an NVIDIA Grace CPU in a single superchip with up to 128GB of unified […]
Nvidia just released a free speech-to-text model that can transcribe up to 40 languages, but it only works on recordings, not live audio, so it’s a big step for meeting and medical transcription tools while still leaving real-time use to rivals like ElevenLabs.

DeepSeek, Google, and NVIDIA build the agent stack
On October 28, reports indicated that OpenAI intends to procure artificial intelligence chips from Google. For a long time, OpenAI has been a major purchaser of NVIDIA GPUs, relying on them for training and inference of large-scale models. As demand for computing power surges, companies are seeking more cost-effective alternatives suitable for running AI models. Google’s self-developed TPU has gradually gained prominence in recent years, emerging as a potential option. This move may reflect a trend toward diversification in AI chip procurement.
